Server log analysis represents the most accurate method for determining how search engines interact with a website. It offers a level of clarity that standard reports often miss by recording every bot request as it happens.
Moving beyond basic metrics allows technical teams to focus on the efficiency of their digital infrastructure. You can see exactly where resources go and how to improve site performance. Keep reading to learn more about strategic log file analysis.
Understanding the Critical Role of Server Log Analysis in Modern SEO
Server log files are the ultimate source of truth for technical SEO. While most tools provide a summarized view of data, raw logs capture every single hit from a search engine bot in real-time. This level of detail isn't available in standard analytics platforms.
Bridging the Gap Between GSC Data and Raw Server Realities
Google Search Console provides a helpful overview of crawling through its Crawl Stats report. However, this data is often sampled or delayed, which can hide significant technical issues. It might miss sudden spikes in bot activity or fail to address specific resource requests that affect site performance.
Server logs fill these gaps by providing precise IP addresses and user agents for every interaction. They show the exact status codes returned for every request made by a bot. This data allows for a more accurate diagnosis of server-side errors that GSC might aggregate or overlook.
Relying solely on third-party reporting tools can lead to a skewed understanding of site health. These tools often use aggregated data that doesn't reflect the minute-by-minute reality of server activity. Accessing raw logs ensures that the data used for decision-making is complete and untampered.
Why Standard Analytics Fail to Capture Bot Efficiency
Client-side analytics tools like Google Analytics are built primarily to track human behavior. They rely on JavaScript to record page views and interactions. Because search engine bots often don't execute JavaScript, they remain invisible to these platforms.
The movements of a crawler through a site's architecture can consume vast amounts of bandwidth without ever appearing in an analytics dashboard. This creates a phenomenon known as ghost traffic, where the server works hard but the cause remains hidden. Without a server-centric view, it's impossible to see the full picture of resource consumption.
Server logs capture every request regardless of whether JavaScript is executed. This makes them the only reliable way to monitor how bots navigate through complex site structures. Relying on client-side tools alone leaves a massive blind spot in your technical strategy.
Defining and Measuring Crawl Budget for High-Performance Sites
Crawl budget is the set of URLs that Google can and wants to crawl. It's determined by two main elements: crawl capacity limit and crawl demand. Google doesn't have an infinite capacity to index every page on the internet, so it must prioritize.
The Core Components of Googlebot Crawl Frequency
Crawl frequency is an important technical signal that reflects how Google understands a site's health. While it doesn't directly boost ranking positions, it's key to ensuring pages are discoverable and up to date. A site that's crawled more frequently is generally perceived as more reliable and relevant.
Server speed plays a massive role in how often Googlebot visits a site. Low latency allows the bot to request more pages in a shorter window. If a server responds slowly, the bot will reduce its crawl rate to avoid crashing the system.
A faster server response time acts as a gateway for better indexing. When the server is healthy and fast, Googlebot feels confident enough to increase its activity. This relationship makes server performance a primary factor in maintaining a high crawl frequency.
Identifying the Threshold of Crawl Demand vs. Site Performance
Google balances its crawl capacity against the crawl demand of a specific site. The capacity limit is determined by the server's ability to handle requests without errors. Crawl demand is based on how much Google believes the content is worth visiting frequently.
Log data helps identify if a bot is backing off due to server errors or a lack of interest. If you see high error rates in the logs, it's a sign that the server is struggling. If errors are low but crawling remains infrequent, the content might be perceived as stale or low-value.
Finding the sweet spot where crawl frequency matches your publishing cadence is the goal of log analysis. You want the bot to show up exactly when you have new information to share. Monitoring logs lets you adjust your strategy to meet this performance threshold.
Executing a Strategic Log File Audit to Spot Waste
Executing a log file audit begins with gathering and cleaning raw data. This step ensures the analysis is based on genuine search engine activity. Raw logs often contain hits from scrapers and fake bots, which can skew results.
Technical Log Acquisition across Environments
The process of log acquisition varies depending on your server environment. If you're running Apache or Nginx, you can often retrieve raw logs directly from the server via SSH or FTP. Large sites using CDNs like Cloudflare or Akamai can stream logs directly into analysis tools for real-time monitoring.
Retaining logs over a long period allows you to spot seasonal trends in bot behavior. You should ensure your server is configured to log the correct data points, including IP addresses and full request strings. This technical specificity provides the foundation for any professional log file analysis for large e-commerce sites.
Tools and Methodologies for Processing Raw Log Files
There are several ways to process large log files, depending on the size of the website. For smaller sites, simple command-line tools or Excel might be enough to find basic patterns. However, these methods quickly become unmanageable as the data volume increases.
Specialized software like the Screaming Frog Log File Analyser offers a more structured approach. This tool can compare log data against a site crawl or an XML sitemap to identify orphaned pages. These are pages that exist and are crawled, but are not reachable through the internal link structure.
Large enterprises might prefer using the ELK stack for continuous log monitoring. This setup allows for real-time analysis and custom dashboards tailored to specific business goals. The right toolset depends on your team's technical proficiency and the site's complexity.
Isolating Non-Commercial Admin Scripts and Dev Folders
Logs often reveal hits on non-public assets, such as WordPress admin scripts or internal development folders. These pages have no commercial value and should not be accessible to search engine bots. Every time a bot hits these files, it wastes a small portion of your crawl budget.
Staging environments that are left open to crawlers can cause significant issues. They often contain duplicate content that confuses search engines and drains resources. Identifying these hits in the logs is the first step toward restricting access.
Restricting these areas ensures that the bot's attention stays on revenue-generating pages. You can use log data to find specific file paths that are being crawled unnecessarily. Cleaning up these paths is an easy win for improving crawl efficiency.
Identifying Common Spider Traps and Crawl Inefficiencies
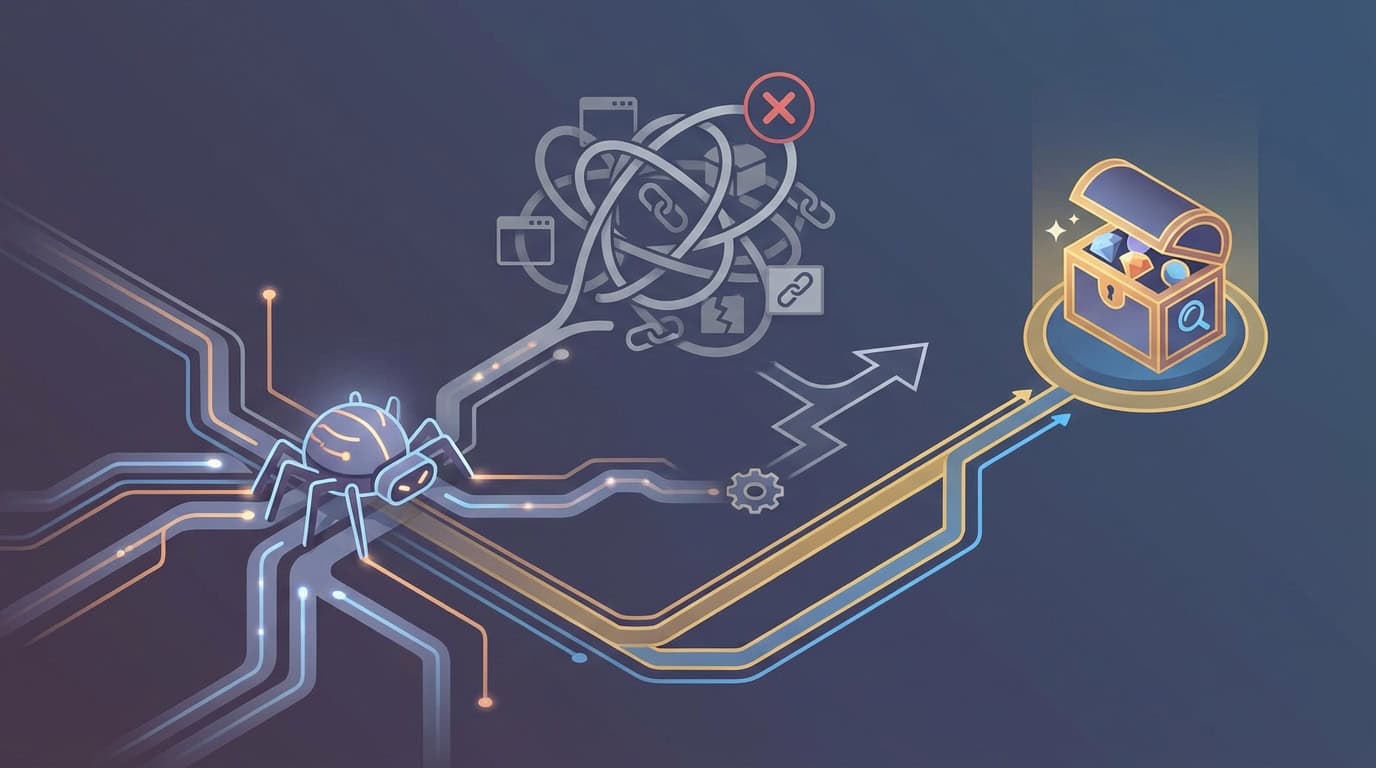
Spider traps are structural issues that cause bots to get stuck in infinite loops. These can include poorly configured calendars, recursive directories, or infinite scrolling features. These traps can consume a massive portion of a crawl budget in just a few hours.
The Hidden Cost of Faceted Navigation and Filtered Views
Faceted navigation accounts for 50% of the crawling challenges Google faces. E-commerce sites often suffer from this because filters for size, color, and price create nearly infinite URL combinations. These combinations provide very little unique value to search engines but require massive crawling efforts.
Log files will show if Googlebot is hitting hundreds of variations of the same category page. You might see patterns where the bot is stuck crawling long lists of filtered results that aren't even indexable. This is a classic example of low-value URLs draining your resources.
Identifying the long tail of these filtered URLs in your logs is important for recovery. Once you see the scale of the problem, you can take steps to limit the bot's access to these combinations. This allows the crawler to focus on your main product and category pages instead.
Managing Infinite Loops and Redirect Chains in Log Data
A site with unchecked spider traps might see its indexation drop as the bot spends time on useless URLs. One real-world case found that a crawler discovered 580,000 indexable pages on a website. Only 197,000 pages were actually in the site structure, leaving 3.7 million orphaned pages that the bot visited.
Redirect chains are another source of crawl friction that can be found in server logs. If a redirect chain contains more than 5 hops, Googlebot will not land on the destination URL. This means the bot never reaches the final destination URL you want it to see.
Every redirect in a chain consumes a small amount of crawl budget. Logs help you identify these patterns by showing repeated status codes for the same request journey. Cleaning up these paths ensures the bot reaches its destination with the least effort possible.
Prioritizing High-Value URLs and Revenue-Generating Assets
Identifying technical waste is only the diagnostic phase of a log audit. Prioritizing your assets is the remedial strategy that turns data into growth. Log analysis should be a commercial strategy that aligns bot behavior with business goals.
Mapping Crawl Patterns to Conversion and Business Goals
The next step is overlaying your crawl frequency data with conversion data from your analytics. This lets you see whether Googlebot is actually spending time on the pages that drive revenue. You might find that your most profitable pages are being neglected by search engines.
Identifying these high-value, low-frequency pages is a priority for any audit. If a page has high conversion potential but isn't being crawled, it won't reach its full ranking potential. You can then investigate why the bot isn't visiting those pages as often as it should.
This framework helps you audit the alignment between SEO traffic and business value. It shifts the conversation from simple crawl counts to profitability. Aligning these two factors is the hallmark of a sophisticated technical SEO audit for enterprise WordPress platforms.
Pruning Low-Value URLs to Conserve Resources
Sites with more than 50,000 pages typically waste 40-60% of their crawl budget on low-value URLs. These include pagination chains, duplicate content, and inefficient plugin-generated pages. Pruning these assets is a strategic way to thin out the site and focus on quality.
The less-is-more philosophy is powerful in technical SEO. By reducing the total number of indexable pages, you can actually increase the overall authority of the pages that remain. It's better to have 10,000 high-quality pages than 100,000 low-quality ones.
Deciding which assets to cut involves looking at both crawl data and performance metrics. If a page is frequently crawled but generates no organic traffic, it's a candidate for removal. Removing these pages frees up the budget for your most important content.
Actionable Tactics to Redirect Googlebot Toward Profitable Content
Identifying waste is only half the battle in a technical log audit. You must also implement tactics to steer Googlebot away from low-value areas. Active management of bot behavior is required to achieve measurable improvements in site performance.
Implementing Advanced Robots.txt Directives and Noindex Tags
The robots.txt file is a powerful tool for hard blocking specific directories or URL patterns. Blocking URLs with robots.txt prevents Google from crawling them. This is the most direct way to stop the bot from wasting time on dev folders or admin scripts.
There's a difference between using robots.txt and using noindex tags. Robots.txt stops the crawl entirely, while noindex allows the crawl but prevents the page from appearing in search results. Choosing the right one depends on whether you want to save crawl budget or manage search visibility.
Strategically implementing these directives ensures that the crawler's resources are preserved for your main content. You should review your logs after making these changes to verify that the bot is following the new rules. Constant monitoring is key to maintaining an efficient site.
Utilizing URL Parameter Tools to Control Bot Behavior
URL parameter settings in search engine webmaster tools can sometimes help manage how bots handle query strings. Action parameters account for 25% of crawling issues on the web today. These settings tell the bot whether a parameter changes the page content or is just for tracking.
However, recent data suggests that only about 1% of the configurations in these tools are truly useful for crawling. You should consider using cleaner permalink hierarchies or fragmented URL structures as a modern alternative. These methods provide more consistent control over bot behavior than legacy tools.
Ensuring that only the canonical version of a page is prioritized for crawling is the ultimate goal. When the bot understands which version is the master copy, it doesn't waste time on duplicates. Managing these settings correctly keeps your index clean and focused.
Request a Technical SEO Infrastructure Audit
Log file analysis is a continuous process that ensures your website remains efficient as it grows. By identifying and eliminating crawl waste, you can focus Googlebot's limited attention on the assets that drive revenue. This technical discipline is the foundation of a high-performance SEO strategy and a competitive advantage in any industry.
I have spent more than 15 years helping businesses analyze and improve their technical SEO infrastructure. My expertise in custom WordPress development and SEO strategy allows me to identify bottlenecks that keep your site from reaching the first page. Contact me today to discuss how a technical SEO infrastructure audit can optimize your site for maximum growth.